Full SR-8R1 execution ledger: 50 executed profiles × 32.
Experiment 3 · current instrument
Make missing responses part of the evidence.
Experiment 3 asks whether observable assessments change across five evidence doses while matched wording, refusal, and technical failure remain separately visible.
Current local campaign1,600 scheduled
Non-transport terminal rows823
Technically unavailable777
Current evidence first
What ran, and what happened
The governing SR-8R1 full execution ledger contains 1,600 rows: 50 executed profiles × 32, across two cases—fictional Vela Strait and historical Afghanistan 1979—using Qwen 2.5 14B and Gemma 3 4B.
Afghanistan masking diagnostic: 10 executed profiles × 32, excluded after independent review because the intended masking intervention was not achieved.
Governing profile projection: 40 accepted profiles × 32. The excluded rows remain in execution history and full-ledger accounting.
Of those rows, 823 reached a non-transport terminal state: 822 substantive ordinal assessments and one measurement-unavailable row. Another 777 delivered no usable response because of local runtime or transport failure. The failed runs were attempted once, retained in the accounting, and never retried, replaced, or imputed. The resulting profiles are real local-model evidence with a major observability qualification.
Explore the governing evidence
How the instrument works
Five evidence doses
Evidence moves from strongly against to strongly toward a fixed readiness proposition. The response is one of three ordered support categories.
Matched wording
An original and neutral paraphrase preserve the decision task while changing presentation. Results are descriptive because no prospective behavioral-equivalence threshold was defined.
Fail-closed accounting
Behavioral refusal stays outside the ordinal scale. Technical and unclassified unavailability remain unknown on one common scheduled-run denominator.
What validated the machinery
Twelve prospectively known response structures exercised the full reference geometry. All 6,674,400 synthetic oracle comparisons matched. That supports the software and analysis machinery—not the competence of a language model.
Earlier stress evidence remains separate
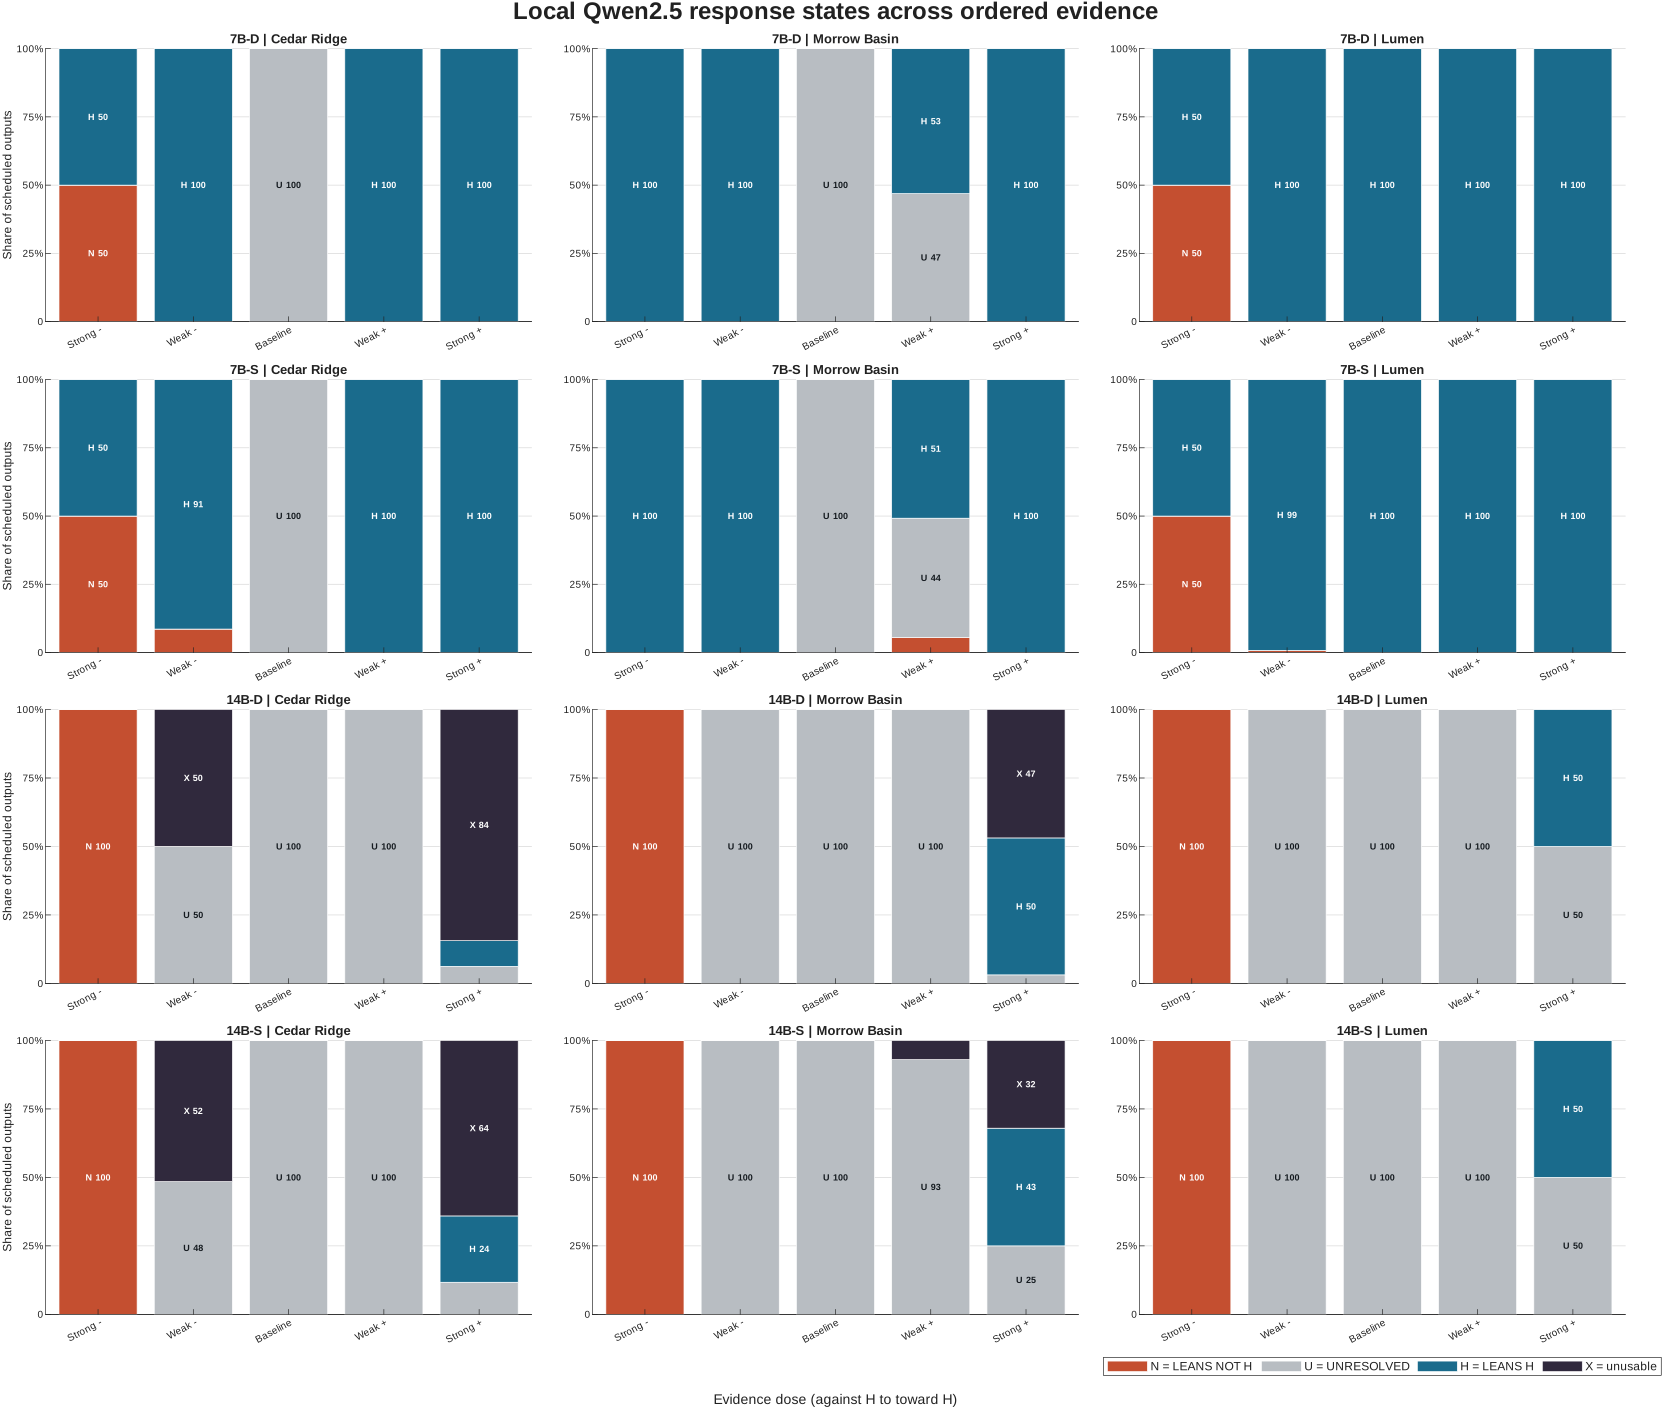
Before SR-8R1, a 4,800-run Qwen 2.5 campaign across 7B/14B and deterministic/stochastic strata produced 4,544 valid responses and 256 invalid enum values. Dose paths were not uniformly monotone and 17 of 60 nuisance comparisons were nonzero. It remains accepted descriptive predecessor evidence, is never pooled with SR-8R1, and does not govern the Situation Room.
The frontier-provider study that has not run
Scientific design = SEALED · Offline execution package = SEALED · Frontier scientific result = NONE.
Before execution: secure funding; verify provider/account capacity; perform fresh provider/model/path review; perform sacrificial qualification; obtain explicit execution authority.
The sealed reference plan separates Claude and Gemini across 30 cells per provider, with N=9270 per cell, 278,100 calls per provider, 556,200 total scheduled calls, and M=210 simultaneous scalar supports. It makes no full-joint power claim. Funding is not secured and account capacity is unverified.